Connection String to OpenAI and OpenAI-Compatible Providers
-
This article explains how to define a connection string to the OpenAI Service,
enabling RavenDB to use OpenAI models for Embeddings generation tasks, Gen AI tasks, and AI agents. -
Use this connection string format to connect RavenDB to any OpenAI-compatible provider that offers a compatible API. As long as the provider follows the OpenAI API format, RavenDB will be able to use it for Embeddings generation, Gen AI tasks, and chat-based agent interactions.
-
The Studio and Client API examples below define a per-database AI connection string.
To define the same provider configuration at the cluster level, see Add a server-wide connection string. -
In this article:
Define the connection string - from Studio
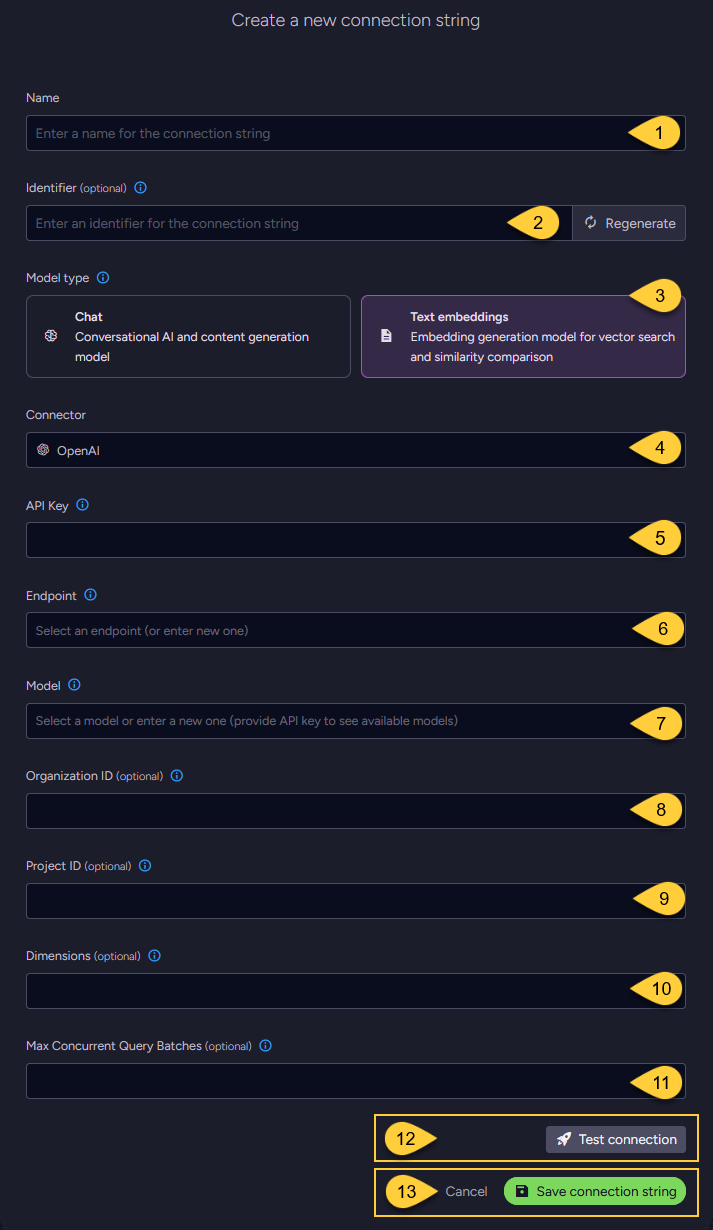
Configuring a text embedding model
-
Name
Enter a name for this connection string. -
Identifier (optional)
Learn more about the identifier in the connection string identifier section. -
Model Type
Select "Text Embeddings". -
Connector
Select OpenAI from the dropdown menu. -
API key
Enter the API key used to authenticate requests to OpenAI or any OpenAI-compatible provider. -
Endpoint
Enter the base URL of the OpenAI API.
This can be the standard OpenAI endpoint or a URL provided by any OpenAI-compatible provider. -
Model
Select or enter the text embedding model to use, as provided by OpenAI or any OpenAI-compatible provider. -
Organization ID (optional)
- Set the organization ID to use for the
OpenAI-Organizationrequest header. - Users belonging to multiple organizations can set this value to specify which organization is used for an API request. Usage from these API requests will count against the specified organization's quota.
- If not specified, the header will be omitted, and the default organization will be billed.
You can change your default organization in your user settings. - Learn more in Setting up your organization
- Set the organization ID to use for the
-
Project ID (optional)
- Set the project ID to use for the
OpenAI-Projectrequest header. - Users who are accessing their projects through their legacy user API key can set this value to specify which project is used for an API request. Usage from these API requests will count as usage for the specified project.
- If not specified, the header will be omitted, and the default project will be accessed.
- Set the project ID to use for the
-
Dimensions (optional)
- Specify the number of dimensions for the output embeddings.
Supported only by text-embedding-3 and later models. - If not specified, the model's default dimensionality is used.
- Specify the number of dimensions for the output embeddings.
-
Max concurrent query batches: (optional)
- When making vector search queries, the content of the search terms must also be converted to embeddings to compare them against the stored vectors. Requests to generate such query embeddings via the AI provider are sent in batches.
- This parameter defines the maximum number of these batches that can be processed concurrently.
You can set a default value using the Ai.Embeddings.MaxConcurrentBatches configuration key.
-
Click Test Connection to confirm the connection string is set up correctly.
-
Click Save to store the connection string or Cancel to discard changes.
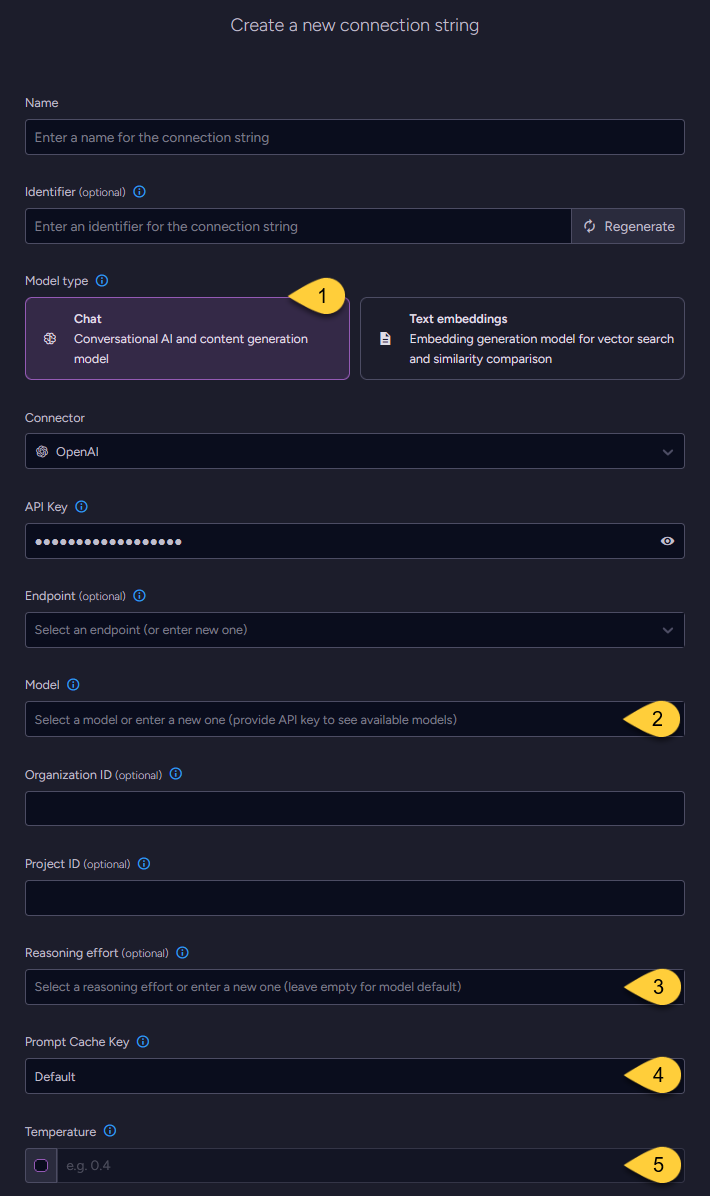
Configuring a chat model
-
When configuring a chat model, the UI displays the same base fields as those used for text embedding models,
including the connection string Name, optional Identifier, API Key, Endpoint, Model name, Organization ID, and Project ID. -
Additional settings specific to chat models are: Reasoning effort, Prompt Cache Key, and Temperature.
-
Model Type
Select "Chat". -
Model
Enter the name of the OpenAI model to use for chat completions. -
Reasoning effort (optional)
-
Controls the amount of internal reasoning performed by supported chat models.
Lower values can reduce latency, while higher values can improve results for complex requests. -
Select one of the listed values or enter a custom value supported by the selected model and provider.
The listed values arenone,minimal,low,medium,high,xhigh, andmax. Supported values vary by model.
For example, OpenAI GPT-5.1 and later models do not supportminimal; usenoneinstead. -
For model names matching GPT-5.4 or later, RavenDB sends
noneeven when no value is selected or another value is configured. RavenDB applies this override to avoid function-tool errors with OpenAI's Chat Completions API. Because the override is based on the model name, it also applies to OpenAI-compatible providers that use a matching name, such asopenai/gpt-5.6-sol. -
For other model names:
- If no value is specified, RavenDB omits
reasoning_effortand the model applies its default. - RavenDB converts only the exact, case-sensitive legacy values
Minimal,Low,Medium, andHighto lowercase before sending them. - All other non-empty values are trimmed and sent without validation or case conversion.
This allows new provider values to be used without waiting for a RavenDB release.
Providers match the value exactly; OpenAI requires lowercase values.
- If no value is specified, RavenDB omits
-
-
Prompt Cache Key (optional)
-
Controls whether RavenDB includes the
prompt_cache_keyfield in chat completion requests sent to the AI provider when using AI Agents. -
When enabled (set to True), RavenDB sends the Conversation's document ID in the
prompt_cache_keyfield with each request. This can help the AI provider identify requests that belong to the same conversation and reuse a previously cached prompt prefix (system prompt + prior messages). -
Why this helps:
AI providers typically process requests on many servers. Without a cache key, consecutive requests from the same conversation may be handled by different servers, each reprocessing the entire conversation from scratch. With the cache key, the provider can route the request to the same machine that handled the previous turn, where the computed prefix is likely still in memory. The provider then only needs to process the new messages, reducing latency and cost. -
The full conversation content is still sent with every request. The cache key is only a provider-side optimization hint. RavenDB does not control the provider's caching behavior.
-
Options:
Default-True(Enabled for OpenAI and OpenAI-compatible providers).True- Always send the cache key.False- Never send the cache key.
Set to False if your provider does not support the field and returns errors instead of ignoring it.
-
-
Temperature (optional)
-
Controls the randomness and creativity of the model's output.
Valid values typically range from0.0to2.0:- Higher values (e.g.,
1.0or above) produce more diverse and creative responses. - Lower values (e.g.,
0.2) produce more focused, consistent, and deterministic output.
- Higher values (e.g.,
-
If no value is specified, RavenDB omits
temperatureand the model applies its default. -
RavenDB does not validate whether the selected model or provider supports
temperature.
When a value is specified, RavenDB sends it to the provider. -
For model names matching GPT-5.4 or later, RavenDB separately forces reasoning effort to
none. OpenAI GPT-5.4 supportstemperatureonly when reasoning effort isnone, so this override keepstemperatureusable for that model. This override does not guarantee that later models or OpenAI-compatible providers supporttemperature. -
OpenAI GPT-5.1 and GPT-5.2 also support
temperatureonly when reasoning effort is set tonone.
Older GPT-5 models do not supporttemperature. Check the provider's documentation for other models. -
See GPT-5.4 parameter compatibility and GPT-5.2 parameter compatibility.
-
Define the connection string - from the Client API
- Connection_string_for_text_embedding_model
- Connection_string_for_chat_model
using (var store = new DocumentStore())
{
    // Define the connection string to OpenAI
    var connectionString = new AiConnectionString
    {
        // Connection string Name & Identifier
        Name = "ConnectionStringToOpenAI",
        Identifier = "identifier-to-the-connection-string", // optional

        // Model type
        ModelType = AiModelType.TextEmbeddings,

        // OpenAI connection settings
        OpenAiSettings = new OpenAiSettings
        {
            ApiKey = "your-api-key",
            Endpoint = "https://api.openai.com/v1",

            // Name of text embedding model to use
            Model = "text-embedding-3-small",

            // Optionally, override the default maximum number of query embedding batches
            // that can be processed concurrently
            EmbeddingsMaxConcurrentBatches = 10
        }
    };

    // Deploy the connection string to the server
    var putConnectionStringOp =
        new PutConnectionStringOperation<AiConnectionString>(connectionString);
    var putConnectionStringResult = store.Maintenance.Send(putConnectionStringOp);
}
using (var store = new DocumentStore())
{
    // Define the connection string to OpenAI
    var connectionString = new AiConnectionString
    {
        // Connection string Name & Identifier
        Name = "ConnectionStringToOpenAI",
        Identifier = "identifier-to-the-connection-string", // optional

        // Model type
        ModelType = AiModelType.Chat,

        // OpenAI connection settings
        OpenAiSettings = new OpenAiSettings
        {
            ApiKey = "your-api-key",
            Endpoint = "https://api.openai.com/v1",

            // Name of chat model to use
            Model = "gpt-5.1",

            // Optionally, set the reasoning effort supported by the selected model.
            // Since GPT-5.1 accepts Temperature only with 'none',
            // this example leaves Temperature unset.
            ReasoningEffort = "low",

            // Optionally, enable or disable prompt prefix caching
            EnablePromptCache = true
        }
    };

    // Deploy the connection string to the server
    var putConnectionStringOp =
        new PutConnectionStringOperation<AiConnectionString>(connectionString);
    var putConnectionStringResult = store.Maintenance.Send(putConnectionStringOp);
}
Syntax
public class AiConnectionString
{
    public string Name { get; set; }
    public string Identifier { get; set; }
    public AiModelType ModelType { get; set; }
    public OpenAiSettings OpenAiSettings { get; set; }
}

public class OpenAiSettings : AbstractAiSettings
{
    public string ApiKey { get; set; }
    public string Endpoint { get; set; }
    public string Model { get; set; }

    public string OrganizationId { get; set; } // default organization is used if not set
    public string ProjectId { get; set; }      // default project is used if not set

    // Relevant only for TEXT EMBEDDING models:
    // Specifies the number of dimensions in the generated embedding vectors.
    public int? Dimensions { get; set; } // optional

    // Relevant only for CHAT models:
    // Controls the randomness and creativity of the model’s output.
    // Higher values (e.g., 1.0 or above) produce more diverse and creative responses.
    // Lower values (e.g., 0.2) result in more focused and deterministic output.
    // If set to 'null', the temperature is not sent and the model's default will be used.
    // RavenDB does not validate model compatibility; it sends any configured value.
    // For model names matching GPT-5.4 or later, RavenDB separately forces
    // reasoning effort to 'none'.
    // OpenAI documents that GPT-5.4 supports temperature only with reasoning effort 'none'.
    // This does not guarantee that later models or compatible providers support temperature.
    // OpenAI GPT-5.1 and GPT-5.2 also support it only with 'none';
    // older GPT-5 models do not support it.
    public double? Temperature { get; set; } // optional

    // Relevant only for CHAT models:
    // Controls the amount of internal reasoning performed by supported models.
    // For model names matching GPT-5.4 or later, RavenDB sends 'none' even when unset.
    // For other model names, null or whitespace omits the setting.
    public string ReasoningEffort { get; set; } // optional

    // Relevant only for CHAT models:
    // Available through the Client API only; it is not exposed in Studio.
    // Makes the model's sampling more reproducible across requests.
    // Does not guarantee deterministic output.
    public int? Seed { get; set; } // optional

    // Relevant only for CHAT models:
    // Controls whether the 'prompt_cache_key' field is included in chat completion requests.
    // When enabled, the conversation's document ID is sent as the cache key to the AI provider.
    // Default: enabled (true) for OpenAI and OpenAI-compatible providers
    public bool? EnablePromptCache { get; set; } // optional
}

public class AbstractAiSettings
{
    public int? EmbeddingsMaxConcurrentBatches { get; set; }
}